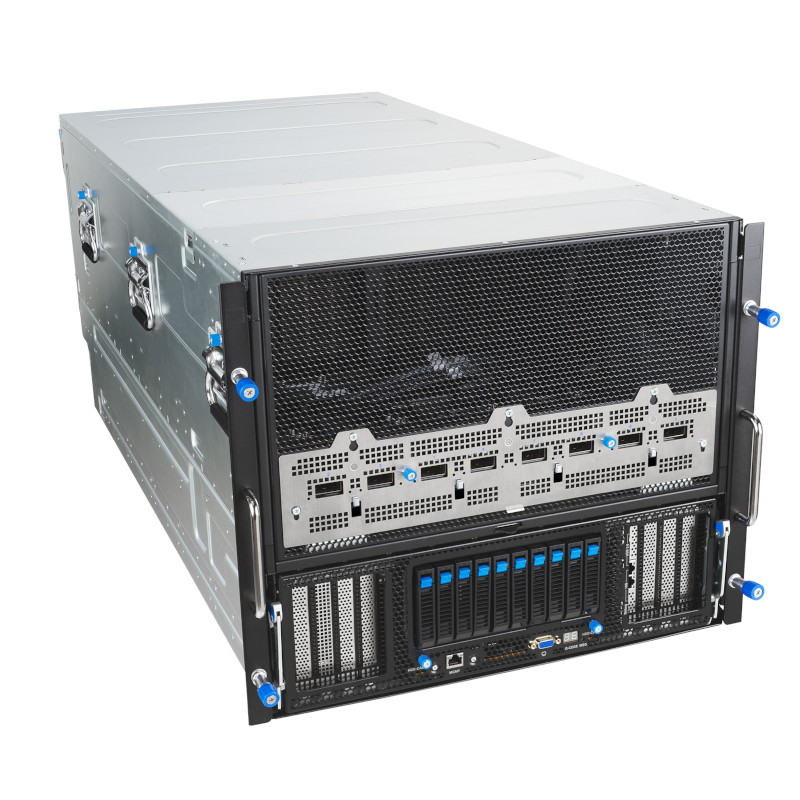
NVIDIA HGX B300 AI Server – Configured to Order in the UK
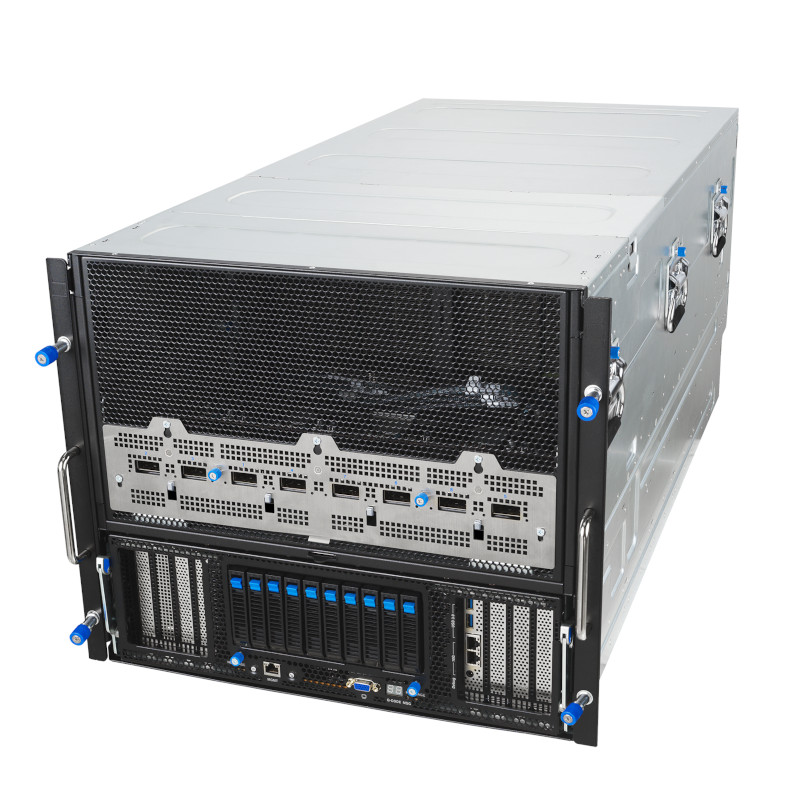
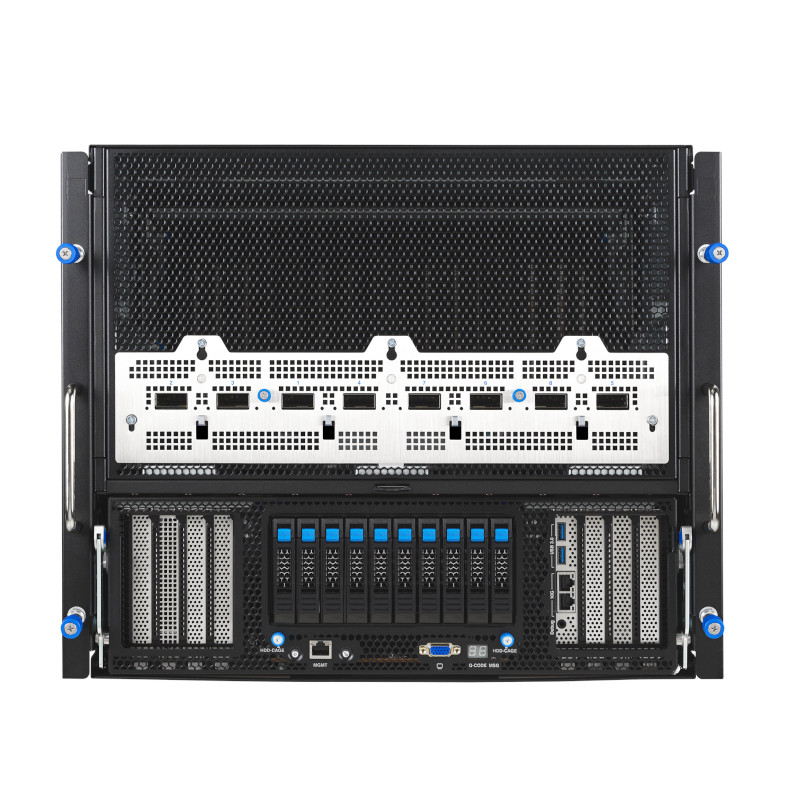
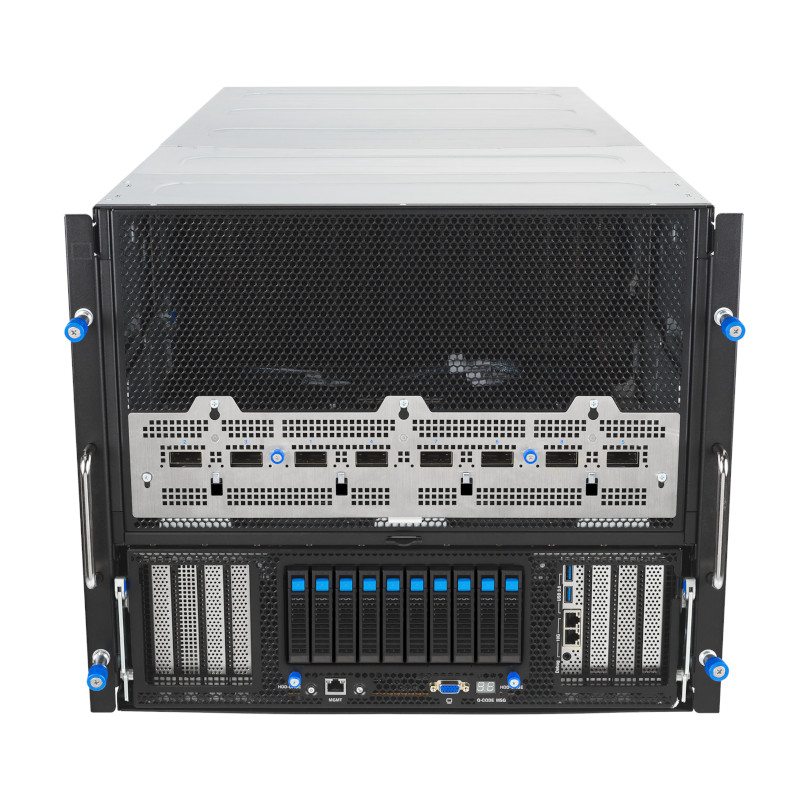
The ASUS XA NB3I-E12 is Punch Technology’s flagship NVIDIA HGX B300 AI Server, built for large-scale model training, fine-tuning and high-throughput inference.
The ASUS XA NB3I-E12 NVIDIA HGX B300 AI Server pairs eight NVIDIA B300 GPUs on the NVIDIA HGX B300 baseboard with dual Intel Xeon 6787P processors, 2TB of DDR5 memory and 800Gb/s of dedicated InfiniBand networking per GPU. As a NVIDIA HGX B300 AI Server, every component is chosen so the CPU, memory and network can keep pace with the GPUs rather than bottleneck them, which matters as soon as a workload spans more than one node.
Please note: due to exceptionally high global demand for NVIDIA Blackwell Ultra platforms, current lead time on this system is approximately 20-25 weeks. Contact us for the latest availability before configuring your order.
Configured to Your Requirements
This listing shows our reference configuration – 2TB of DDR5 memory and a 2 x 7.68TB NVMe RAID OS volume. RAM and storage can be configured to order, so if this configuration does not match your workload, contact us for a custom quote built around your exact memory and storage requirements. The chassis, CPU, GPU baseboard, networking and power supply ship as a complete pre-built unit direct from ASUS and are not user-configurable.
Compute
Eight NVIDIA B300 (Blackwell Ultra) GPUs sit on a single NVIDIA HGX B300 baseboard, sharing 2.3TB of HBM3e memory (288GB per GPU). The eight GPUs are linked by fifth-generation NVIDIA NVLink through dual NVSwitches, giving 1.8TB/s of GPU-to-GPU bandwidth and 62TB/s of aggregate memory bandwidth across the platform. A single B300 can hold a 70-billion parameter model without quantisation, with memory to spare for KV cache and batch processing, which makes the full 8-GPU platform suited to training and serving the largest current open models.
Processor and Memory
Dual Intel Xeon 6787P processors (86 cores / 172 threads each, up to 3.8GHz turbo) handle data pre-processing and orchestration around the GPUs. 2TB of DDR5-6400 ECC RDIMM memory is fitted across all 32 DIMM slots, expandable up to 4TB with currently validated 128GB modules.
Networking
Every GPU has its own dedicated NVIDIA ConnectX-8 SuperNIC, running at up to 800Gb/s, for eight independent InfiniBand links rather than one shared connection.
Storage and Power
Two 7.68TB 2.5-inch NVMe SSDs form a RAID OS/boot volume managed by an onboard Broadcom 9520 Tri-Mode storage controller, with eight further hot-swap bays available for data-cache drives. Ten hot-swap 3200W 80 PLUS Titanium power supplies, in a 5+5 redundant configuration, keep the platform running through a single PSU failure.
Ideal for
- Large language model training and fine-tuning (Llama, DeepSeek, Mistral, Qwen and similar model families)
- High-throughput inference serving with vLLM, NVIDIA NIM or Triton Inference Server
- Distributed training with PyTorch, DeepSpeed, Megatron-LM or NVIDIA NeMo
- Enterprise and research teams scaling AI infrastructure beyond a single node
Whether you are configuring your first dedicated AI training platform or adding capacity to an existing cluster, the NVIDIA HGX B300 AI Server gives you eight GPUs, 2.3TB of shared GPU memory and dedicated per-GPU networking in a single 9U chassis, configured, tested and supported (on-site) by ASUS with additional support from Punch Technology in the UK.
Punch Technology are backed by over 30 years of experience specifying and delivering enterprise PC, workstation and AI server systems.
Full Specification
| Processor | |
| CPU | 2 x Intel Xeon 6787P |
| Cores / Threads | 86 Cores / 172 Threads (each CPU) |
| Frequency | Base 2.0GHz / Max Turbo 3.8GHz |
| Cache | 336MB L3 (each CPU) |
| Memory & Storage | |
| RAM | 2048GB DDR5 6400MHz ECC RDIMM (configurable to order) |
| Configuration | 32 x 64GB (16 DIMMs per CPU) |
| Max Supported | 4TB with currently validated 128GB DIMMs (32 x 128GB); ASUS’s own configuration guidance lists an 8TB theoretical ceiling using 32 x 256GB DIMMs |
| Primary Storage | 2 x 7.68TB 2.5″ NVMe SSD (RAID OS/boot volume, configurable to order) |
| Storage Controller | Broadcom 9520 Tri-Mode Controller |
| Optical Drive | None |
| GPU / Compute | |
| GPU | 8 x NVIDIA B300 (Blackwell Ultra), 288GB HBM3e each |
| Total GPU Memory | 2.3TB HBM3e (288GB x 8 GPUs) |
| GPU Interconnect | 5th Gen NVIDIA NVLink, 1.8TB/s GPU-to-GPU, 14.4TB/s total NVLink bandwidth |
| Aggregate Memory Bandwidth | 62TB/s |
| Display Outputs | None (headless compute GPUs) |
| Networking & Management | |
| GPU Networking | 8 x NVIDIA ConnectX-8 SuperNIC, 800Gb/s per GPU (InfiniBand, auto-negotiates 800/400/200/100Gb/s) |
| Management LAN | Dual 10GbE (Intel X710-AT2) |
| Remote Management | ASUS ASMB11-iKVM (ASUS’s own datasheet spec table lists ASMB12-iKVM — please confirm the exact revision) |
| Security | Trusted Platform Module 2.0 (TPM 2.0) |
| Expansion & Internal Slots | |
| PCIe Slots | 4 x PCIe 5.0 (SKU1 configuration — inferred from the Broadcom 9520 RAID controller fitted; please confirm SKU against your distributor quote) |
| Storage Expansion | 10 x 2.5″ hot-swap NVMe bays total (2 used for RAID OS, 8 free for data-cache drives) |
| Power, Chassis & Cooling | |
| Power Supply | 10 x 3200W 80 PLUS Titanium, 5+5 Redundant |
| Chassis | ASUS XA NB3I-E12, 9U Rackmount |
| Cooling | Air-cooled |
| Dimensions | 394.5mm (H) x 447mm (W) x 945mm (D) |
| Weight | 120kg net / 150kg gross |
| Software & Support | |
| Operating System | RedHat Enterprise Linux, Rocky Linux, Ubuntu or VMware [NEEDS YOUR INPUT – which ships as default] |
| Management Software | ASUS Control Center (ACC) Data Centre Edition, 3 Year License (FOC) |
| Warranty Cover | 3 Years On-Site Service, Next Business Day (ASUS NB3I-OSS(NBD)-36M, L/WW) |
| Lead Time | Approximately 20-25 weeks (subject to change – contact us for current availability) |
What is the ASUS XA NB3I-E12 best for?
The ASUS XA NB3I-E12 is primarily an AI training and inference platform for organisations working with models too large for a single-GPU or 2-4 GPU system. Its 2.3TB of shared HBM3e memory across 8 NVIDIA B300 GPUs is large enough to train and fine-tune large language models such as Llama 3, DeepSeek and Mistral at full parameter counts, and its 8 independent 800Gb/s InfiniBand links make it a practical building block for a multi-node cluster rather than a single-server ceiling.
Common deployments include LLM fine-tuning and post-training, retrieval-augmented generation pipelines that need fast local inference, and research teams running distributed training jobs with PyTorch, DeepSpeed or NVIDIA NeMo across multiple GPUs simultaneously. It is equally suited to enterprise inference serving, where consistent low-latency responses across many concurrent users matter more than raw training throughput.
Where does the ASUS XA NB3I-E12 sit in the range?
For teams whose GPU memory needs are smaller, our Multi-GPU Servers range covers 2 to 8 GPU configurations built around NVIDIA RTX PRO and H200 NVL cards at a lower entry price. For teams needing a fully managed, NVIDIA-supported appliance rather than a configurable server, our NVIDIA DGX Station GB300 systems are the desk-side alternative. The ASUS XA NB3I-E12 sits above both as our highest-density, highest-memory rack platform, built to the same HGX B300 GPU baseboard as NVIDIA’s own DGX B300 appliance but in a more efficient 9U chassis.
Frequently Asked Questions
What is the lead time on the NVIDIA HGX B300 AI Server?
Current lead time is approximately 20-25 weeks, due to exceptionally high global demand for NVIDIA Blackwell Ultra platforms. Contact our team for the latest availability before placing your order.
Is the NVIDIA HGX B300 AI Server configurable?
RAM and storage are configurable to your requirements. This listing shows our reference configuration – 2TB of DDR5 memory and a 2 x 7.68TB NVMe RAID OS volume – as supplied by ASUS. If you need a different memory or storage configuration, contact us for a custom quote. The chassis, CPU, GPU baseboard, networking and power supply are a complete pre-built unit from ASUS and are not user-configurable.
What software and frameworks does the NVIDIA HGX B300 AI Server support?
The system runs standard NVIDIA CUDA-based AI software, including PyTorch, TensorFlow and JAX for model development, DeepSpeed, Megatron-LM and NVIDIA NeMo for distributed training, and vLLM, NVIDIA NIM or Triton Inference Server for production inference. Any Linux-based AI stack built on NVIDIA’s CUDA toolkit is supported.
How much GPU memory does the ASUS XA NB3I-E12 have?
The system has 2.3TB of total GPU memory, made up of 288GB of HBM3e on each of the 8 NVIDIA B300 GPUs, linked by fifth-generation NVIDIA NVLink at 1.8TB/s of GPU-to-GPU bandwidth. This is large enough to hold most current open large language models at full precision without splitting them across multiple systems.
Can multiple NVIDIA HGX B300 AI Server units be networked together?
Yes. Each of the 8 GPUs has its own dedicated NVIDIA ConnectX-8 SuperNIC, giving 8 independent 800Gb/s InfiniBand links per server. This is designed specifically for multi-node clusters, where several servers train a single large model together rather than running independently.
Who is this server best suited for?
The NVIDIA HGX B300 AI Server is best suited to enterprises, research institutions and AI-focused teams training or fine-tuning large language models, running high-throughput inference at scale, or building out a multi-node GPU cluster. It is not intended for single-user workstation use or smaller inference workloads, where our Multi-GPU Servers range is more cost effective.
What support comes with the NVIDIA HGX B300 AI Server?
ASUS 3-year on-site next-business-day service and Punch technical support